Data Pipeline 101: How It Works and Why It Matters
Manual data movement often starts as a practical solution. Someone exports a file, updates a spreadsheet, or copies customer details into another application. As the business grows, that process becomes harder to manage. Records go missing. Values become inconsistent. Reports take longer to prepare. A data pipeline replaces repetitive handoffs with an automated flow between databases, SaaS platforms, APIs, files, and business applications. It can clean information, validate required fields, identify changes, and send updates on a schedule or in real time. Whether you need to connect Salesforce and QuickBooks, sync ecommerce and ERP data, or replicate database changes, this guide outlines the options and steps to consider.
Key Takeaways
- Automate data movement across business systems: Data pipelines connect platforms such as Salesforce, QuickBooks, Microsoft D365, Shopify, databases, and reporting tools, reducing duplicate entry and manual exports.
- Match the pipeline type to your workflow: Use batch processing for scheduled workloads, streaming or CDC for timely updates, and one-way or bidirectional synchronization based on data ownership and collaboration needs.
- Prioritize accuracy, visibility, and recovery: Apply field mappings, validation, deduplication, monitoring, access controls, retries, and reconciliation to keep connected data dependable.
What Is a Data Pipeline?
A data pipeline is a set of automated steps that moves data from one system to another and prepares it for use. It can collect information from databases, SaaS platforms, APIs, files, and other sources, then clean, transform, validate, and deliver that information to a destination.
The destination may be a data warehouse for reporting, an operational database, or a business application that needs current records. Data pipelines help businesses reduce manual data entry, maintain consistent information, and deliver data where teams need it. As Rudderstack explains, pipelines ensure the right data reaches the right system at the right time.
A pipeline can support a single scheduled transfer or a complex, real-time workflow across multiple applications. Its structure depends on the data involved, the required processing steps, and how quickly the destination needs updates.
Define a data pipeline
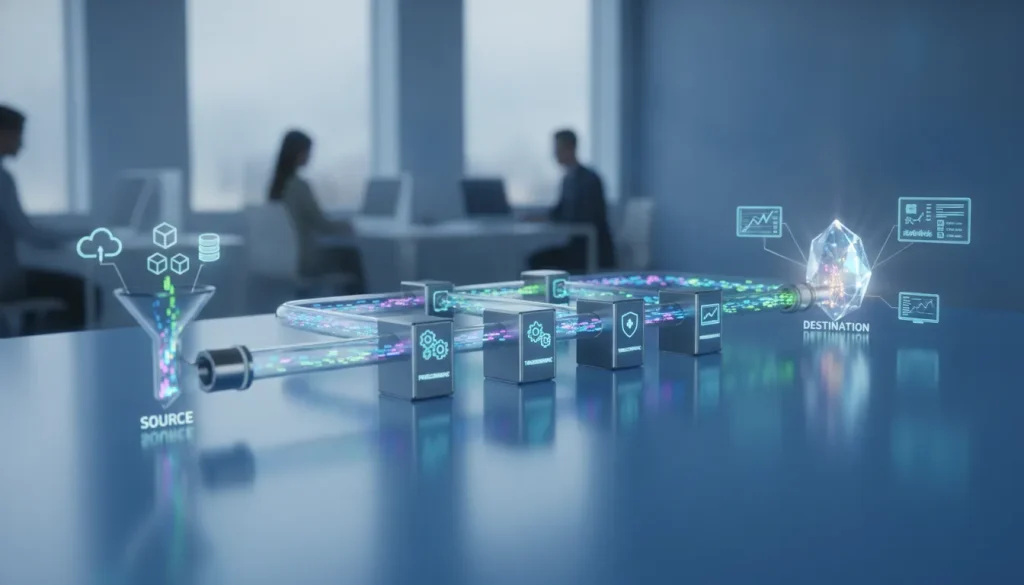
Think of a data pipeline as a repeatable route for information. Data enters through one or more sources, passes through automated processing steps, and arrives at a destination in a usable format.
Those steps might include filtering records, changing field names, converting data types, checking required values, or combining information from multiple systems. For example, a pipeline could collect customer records from Salesforce, standardize the fields, and send them to a reporting database.
A pipeline does not need to be complicated. It might transfer a daily CSV file to a warehouse or process database updates as they occur. The defining features are a clear data path, repeatable actions, and a specific business or technical purpose. This guide to data pipelines explains how they support analytics and operations.
Identify sources, processes, and destinations
Every data pipeline has three core parts: sources, processes, and destinations.
Sources are the systems that create or store data. They may include a CRM such as Salesforce, an accounting platform such as QuickBooks, an ERP, a database, an API, or a file repository. Processes determine what happens to the data after it is collected. A pipeline may remove duplicates, standardize addresses, validate required fields, or enrich customer records with information from another system.
Destinations receive the processed data. A destination might be a warehouse for analysis, an application for daily operations, or a database used by internal teams. Defining these parts before development makes the workflow easier to plan. It also clarifies which records should move, how they should change, and where they should go.
Compare pipelines with basic data transfers
A data pipeline can be as simple as an automated file transfer. If a process moves a file from one location to another on a schedule, it still qualifies as a pipeline, even when the file remains unchanged. Transformation is common, but it is not required.
More advanced pipelines perform several actions before delivery. For example, a pipeline might pull orders from Shopify, match them with customer records in a CRM, convert currencies, remove duplicate entries, and send the finished data to an analytics platform.
The important distinction is whether the transfer follows a defined, repeatable process. A one-time manual export is simply a transfer. An automated process with scheduled movement, validation, monitoring, or delivery rules functions as a data pipeline. As data engineers discuss, even a simple file transfer can fit the definition.
Choose a linear, modular, or event-driven architecture
The right architecture depends on data volume, processing requirements, and how quickly systems need updates.
A linear pipeline follows a fixed sequence, such as extracting data, transforming it, and loading it into a warehouse. It works well for straightforward jobs. A modular pipeline divides the workflow into reusable components. Teams can then apply the same validation or transformation step across several data flows, which simplifies maintenance.
An event-driven pipeline responds when something happens, such as a new order, updated customer record, or changed database row. Instead of waiting for a scheduled run, it processes the update as it occurs. This approach suits workflows that require low latency.
Many organizations use more than one architecture. A nightly reporting pipeline may be linear, while customer updates between operational systems use modular or event-driven processes. These examples of pipeline architectures show how design choices vary by workflow.
Connect business systems with data pipelines
Connected business systems give teams a shared view of important information. Without a pipeline, employees may export records, update spreadsheets, and re-enter data across applications. This manual work takes time and can create mismatched values, duplicate records, and outdated information.
A pipeline can connect CRM, accounting, ERP, and commerce platforms so updates move automatically between them. For example, DBSync’s Salesforce integration helps organizations connect Salesforce data with other business systems, while its QuickBooks integration supports connected accounting workflows.
The connection can be one-way, with data moving from a source to a destination, or bidirectional, with updates shared between systems. With the right rules for field mapping, validation, and error handling, pipelines help operational teams and reporting tools work from consistent, timely records.
How Does a Data Pipeline Work?
A data pipeline moves information through a repeatable series of steps. It collects data from one or more sources, prepares it for use, stores it in the right destination, and delivers it to the people or systems that need it.
A pipeline may run on a schedule, process events as they happen, or combine both approaches. It can also manage task dependencies, validate records, retry failed actions, and alert teams when something goes wrong. This makes it easier to keep information consistent across systems such as Salesforce, QuickBooks, Microsoft D365, Shopify, databases, and analytics platforms.
Ingest data from databases, APIs, SaaS platforms, and files
Data ingestion is the first step in a pipeline. The pipeline connects to source systems and collects raw information, such as customer records from a CRM, invoices from an accounting platform, orders from an ecommerce store, or events from an application.
Common sources include SQL databases, REST APIs, SaaS applications, event streams, spreadsheets, CSV files, and other flat-file formats. An initial load may collect every available record. Later runs can capture only new or changed records, which reduces unnecessary processing and keeps connected systems current.
Connectors can manage authentication, API requests, pagination, and data transfer. For example, a Salesforce integration can transfer CRM records to another business system without requiring employees to copy data manually.
Transform data through cleaning, validation, standardization, and enrichment
Raw data rarely arrives in a format that every system can use. Transformation prepares information by removing duplicates, correcting errors, validating required fields, and applying business rules. It can also standardize timestamps, currencies, names, addresses, and other values.
A pipeline may enrich records by adding information from another source, calculating new fields, or combining related records. For example, it could match a Salesforce customer record with a QuickBooks invoice to create a more complete account view.
These steps help maintain consistency across applications. Well-designed data pipeline practices also include checks for missing values, unexpected formats, schema changes, and unusual record counts before data reaches its destination.
Store data in warehouses, lakes, databases, and applications
Once data has been transformed, the pipeline sends it to one or more destinations, sometimes called data sinks. The best destination depends on how the information will be used. A data warehouse may support reporting and business intelligence, while a data lake can store large volumes of raw or semi-structured data.
Operational databases and business applications serve a different purpose. They hold information that employees and automated processes need for daily work. For example, customer data may move from a CRM into an accounting platform, while order details flow from an ecommerce system into an ERP.
A pipeline can write to multiple destinations at the same time. AWS explains how pipelines move data between warehouses, lakes, and other systems for storage and use.
Deliver data for analytics and operational workflows
A data pipeline creates value when people and systems can act on the information it delivers. Analysts may use prepared data for dashboards, forecasting, customer reporting, and performance analysis. Operational teams may use it to update records, trigger notifications, create invoices, or coordinate fulfillment.
Delivery can happen in batches or continuously. A scheduled pipeline might update a reporting warehouse every night, while a real-time pipeline sends a customer status change to another application within seconds. Some workflows also need bidirectional movement, allowing updates to travel between systems instead of flowing in only one direction.
For example, a QuickBooks integration can synchronize financial information with connected business applications. This helps reduce delays between operational activity and accounting records.
Orchestrate dependencies, schedules, and retries
Most pipelines include several tasks that must run in a specific order. Data may need to be extracted before it can be transformed, and transformation may need to finish before loading begins. Orchestration coordinates these dependencies so each task starts at the right time.
It can also manage schedules, parallel tasks, conditional logic, and retries. If an API temporarily stops responding, the pipeline can retry the request instead of failing the entire workflow. If validation identifies invalid records, the pipeline can send them to an error process for review.
Tools such as Apache Airflow and Prefect provide orchestration features. DBSync’s Cloud Workflow helps teams manage repeatable processes across connected business applications from one platform.
Monitor freshness, lineage, quality, and pipeline health
Monitoring shows whether a pipeline is running correctly and whether its output can be trusted. Teams commonly track job status, run duration, record volume, throughput, error rates, and data freshness. These metrics can reveal a stalled process, an unexpected drop in records, or a growing delay between source and destination.
Data lineage shows where information came from, how it changed, and which systems use it. Quality checks can identify missing fields, duplicate records, schema changes, and unusual values before they affect reports or business processes.
Clear alerts help teams respond before a small issue becomes a larger one. A data replication platform can also help monitor database changes, replication status, and synchronization health across connected systems.
Which Data Pipeline Type Fits Your Needs?
The best data pipeline depends on how your business uses information, how quickly updates must arrive, and whether data needs to move in one direction or both. A finance team preparing a nightly report has different requirements from an operations team that needs inventory changes reflected across sales channels within seconds.
Start with these questions:
- How quickly must the data arrive? Batch processing works for scheduled updates, while streaming supports near real-time events.
- How much data must the pipeline handle? Large historical loads are often more efficient in batches. Smaller, continuous updates may work better with streaming.
- Where does the data need to go? A one-way pipeline feeds one or more destinations. A bidirectional pipeline shares changes between connected systems.
- Which system owns each record? Clear ownership helps prevent conflicting updates and accidental overwrites.
These choices can work together. A business might use batch processing for an initial data load, change data capture for ongoing database updates, and bidirectional synchronization between its CRM and accounting platform. The right design depends on latency, volume, data direction, recovery requirements, and the capabilities of your source and destination systems.
Use batch data pipelines
Batch pipelines collect data and process it at scheduled intervals. For example, a pipeline might extract sales records from an ecommerce platform every night, clean the records, and load them into a data warehouse before the morning reporting cycle.
This approach works well when information does not need to be available immediately. Common examples include payroll processing, monthly financial reporting, historical imports, and overnight inventory reconciliation. Running jobs during off-peak hours can also reduce the effect on source systems. IBM’s overview of data pipelines explains how batch processing groups records and runs them according to a defined schedule.
Batch pipelines are often easier to test and manage than continuously running processes. They can also process large volumes efficiently in a single job. The tradeoff is latency. If a customer updates an order and another system must respond immediately, waiting for the next scheduled run may create outdated information or unnecessary manual work.
Use streaming and real-time data pipelines
Streaming pipelines process data continuously, or shortly after an event occurs. Instead of waiting for a scheduled job, the pipeline responds when something happens, such as a new sale, payment, customer update, or inventory change.
This model supports use cases where timing matters. A retailer can update product availability as orders arrive, while a financial services company can review transactions for suspicious activity. Operations teams can also use streaming data for live dashboards, alerts, and service monitoring.
Streaming does not always mean zero delay. Many systems process events within seconds or minutes, depending on the source, destination, and transformation steps. Streaming pipelines also need careful monitoring because a stalled connection or processing error can affect every event that follows. IBM’s guidance on streaming pipelines covers applications such as sales tracking, fraud detection, and live monitoring.
Combine batch and streaming with hybrid pipelines
Hybrid pipelines combine scheduled processing with continuous event processing. They are useful when a business needs both a complete historical view and fast access to current changes.
For example, a company might use batch processing to load years of customer and order history into a warehouse. It could then use a streaming layer to send new transactions to operational dashboards as they happen. The batch layer provides a dependable foundation, while the streaming layer keeps current information available between scheduled runs.
This structure can also help recover from gaps or processing failures. A team may replay a historical batch to rebuild a destination, then use streaming events to catch up with recent changes. The tradeoff is additional complexity. Both processing paths need compatible schemas, transformation rules, monitoring, and recovery procedures. Lambda architecture is one example of a design that combines batch and streaming layers.
Replicate databases with change data capture
Change data capture, or CDC, tracks inserts, updates, and deletes in a source database, then sends those changes to another system. Instead of repeatedly copying every record, a CDC pipeline focuses on what changed since the last successful update.
This makes CDC useful for database replication, operational reporting, application migrations, and keeping a warehouse current. It can reduce repeated queries on the source database and shorten the time required to update downstream systems. For example, a change to a customer record in an operational database can be published as an event and applied to an analytics database soon afterward.
CDC is a strong option when the source database is the system of record and downstream systems need timely updates. It still requires rules for ordering, deletes, duplicate events, and schema changes. Teams should also plan the initial full load before incremental changes begin. IBM describes CDC as a way to publish database changes as events, often as part of a streaming pipeline.
For businesses that need database replication across connected applications, DBSync’s CDC and Database Replication capabilities help move changes between systems while reducing manual exports and imports.
Move data through one-way pipelines
A one-way pipeline sends data from one source to one or more destinations. The source may be a CRM, accounting system, database, SaaS application, or file repository. The pipeline extracts the data, applies the required transformations, and delivers the result to another platform.
This pattern works well when one system owns a particular type of information. For example, Salesforce may be the source for customer accounts, while a data warehouse receives copies for reporting. An accounting platform can also send financial records to a reporting database without receiving changes in return.
One-way pipelines are generally easier to manage because they have a clear direction and system of record. They can also prevent accidental overwrites in the source application. However, the destination may become outdated if updates are delayed or fail. A reliable pipeline should include validation, error handling, and alerts when records do not arrive as expected. A data pipeline moves information from sources to destinations through a series of automated processing steps.
Synchronize data with bidirectional pipelines
Bidirectional pipelines allow data to flow between two systems. When a record changes in one application, the pipeline sends the relevant update to the other application, helping both platforms maintain a consistent view.
This approach is useful when teams work across systems and need updates available wherever they operate. A sales representative might update a customer in Salesforce, while an accounting team manages billing details in QuickBooks. A bidirectional integration can share the appropriate changes without forcing either team to re-enter information.
Bidirectional synchronization requires more planning than a one-way flow. You need clear ownership for each field, rules for resolving conflicts, and safeguards against update loops. If both systems change the same phone number, for example, the pipeline must know which value to keep or whether to flag the record for review. Bidirectional data pipelines work best when synchronization rules are defined before implementation.
DBSync supports real-time, bidirectional synchronization for businesses that need connected applications to share accurate information without relying on manual exports and imports.
Choose based on latency, volume, and data direction
Use batch processing when data can arrive on a schedule and the workload involves large volumes, historical records, or resource-intensive transformations. Use streaming when applications, teams, or customers need updates shortly after events occur. Choose CDC when you need to capture database changes efficiently instead of repeatedly copying full tables.
Then consider direction. A one-way pipeline is usually the clearest option when one application owns the data and another system only needs a usable copy. A bidirectional pipeline is more suitable when teams update related records across multiple applications and need those changes shared between them.
Your decision also depends on the consequences of delay or inconsistency. A few hours of latency may be acceptable for a monthly report, but not for inventory availability or payment status. Similarly, a one-way flow may be safer for financial records, while two-way synchronization may be necessary for customer and order data shared across CRM, accounting, ERP, and commerce platforms.
Before selecting an architecture, document the required latency, data volume, source-system limits, recovery needs, security requirements, and ownership rules. This gives your team a practical basis for choosing between batch, streaming, CDC, one-way pipelines, and bidirectional synchronization.
Why Use Data Pipelines for Connected Business Systems?
A data pipeline gives business systems a dependable way to exchange information without asking employees to copy and paste records between applications. It can collect data from a CRM, accounting platform, ERP, ecommerce store, or database, apply defined rules, and deliver the results where they are needed.
This matters when several systems support the same business process. Sales may work in Salesforce, finance may rely on QuickBooks, operations may use Microsoft D365, and ecommerce teams may manage orders in Shopify. Without a reliable connection, each department can end up with different customer details, duplicate records, or reports that take hours to assemble.
Pipelines can support scheduled transfers, real-time updates, or a combination of both. They can also include validation, error handling, monitoring, and access controls. This turns data movement into a repeatable process that reduces administrative work and gives teams more dependable information for daily operations.
Automate data movement and reduce manual entry
Manual data entry consumes time and creates opportunities for mistakes. An employee might mistype an account number, overlook a new order, or update one application without changing another. These errors can spread when sales, finance, fulfillment, and customer service all rely on the same records.
A data pipeline automates this movement. It extracts information from a source, transforms it into the format a destination expects, and sends it to the appropriate system. For example, a new customer in a CRM could flow into an accounting platform, while a completed order could move from an ecommerce store to inventory or fulfillment software.
This follows the core definition of a data pipeline, which extracts, transforms, and delivers data for storage, analysis, or operational use. Teams spend less time maintaining spreadsheets and more time reviewing exceptions, improving processes, and supporting customers.
Improve data quality, consistency, and integrity
Connected systems are only useful when the information moving between them is accurate and consistent. Differences in field names, date formats, customer identifiers, or product codes can lead to duplicate records and unreliable reports. A pipeline addresses these issues by applying the same rules each time data moves.
Those rules might standardize phone numbers, convert currencies, validate required fields, or match records across systems. A pipeline can also reject incomplete data, flag unusual values, and keep a record of what changed. This helps teams correct problems before they affect customers, orders, or financial reporting.
Automated pipelines help enforce data consistency by sending the right information to the right system at the right time. Rather than asking employees to remember every formatting rule, you can define the rules once and apply them across recurring workflows.
Deliver timely reporting and operational visibility
Reports lose value when the data behind them is outdated or assembled from disconnected spreadsheets. Leaders may see one sales total in a dashboard, another in an accounting report, and a third in the CRM. Teams then spend time comparing figures instead of acting on them.
A data pipeline keeps reporting systems supplied with current, structured information. It can move sales, customer, product, support, and financial records into a warehouse or reporting database on a schedule that fits the business. Streaming and change data capture can provide updates as events occur.
This creates a clearer view of performance and operations. Teams can monitor order volume, review sales activity, identify unpaid invoices, or spot inventory changes without waiting for a manual file. As Mu Sigma explains, a strong pipeline turns raw business activity into reliable assets for decision-making.
Connect CRM, accounting, ERP, and commerce platforms
Most organizations depend on several applications rather than one central system. Customer information may begin in Salesforce, invoices may be managed in QuickBooks, inventory may sit in an ERP, and orders may arrive through Shopify. Data pipelines connect these systems so each team can access the records required for its work.
For example, a sales opportunity can become a customer record and then flow into accounting when a deal closes. Order details from an ecommerce platform can go to an ERP for fulfillment, while payment status can return to the customer-facing system. These connections reduce delays caused by email attachments and manually updated spreadsheets.
DBSync supports workflows between business applications through Salesforce integration and QuickBooks integration. The right design depends on the systems involved, the fields being shared, and whether updates should move in one direction or both.
Give teams faster access to trusted data
Employees work more efficiently when they can find dependable information in the systems they already use. Sales representatives need current account details, finance teams need accurate transaction records, and support agents need a complete view of customer activity. If accessing that information requires a request to another department, routine work slows down.
A well-designed pipeline delivers approved data to the right destination with fewer delays. It can organize records, apply business rules, and make updates available without requiring every employee to run a query or reconcile several files. Permissions still determine who can see or change information, while the pipeline handles repeatable movement.
This gives teams more confidence in their work. They can spend less time checking whether a record is current and more time using it. MessageGears describes how effective data flows can give teams greater autonomy to work with trusted information under the right permissions.
Support analytics, machine learning, and scalable operations
Data pipelines support more than application updates. They also prepare information for analytics, forecasting, customer segmentation, and machine learning. Before data can support these use cases, it often needs to be collected from several sources, cleaned, standardized, and stored in a format that analytical tools can use.
A pipeline performs these steps consistently as data volumes grow. It might send operational records to a warehouse for dashboards, stream events to a monitoring service, or prepare historical data for a predictive model. The same foundation can support a small reporting workflow now and a larger data program later.
Pipelines also help organizations scale without adding the same amount of manual effort. New sources, destinations, and transformation rules can become part of a structured process instead of another spreadsheet. They form the operational backbone of the modern data stack, supporting dashboards, machine learning models, and customer-facing activities.
Create reusable, governed data workflows
A pipeline becomes more valuable when teams can reuse its logic across multiple processes. Instead of creating a separate script for every integration, an organization can define shared rules for matching customers, validating products, handling errors, and recording changes. Reusable components are easier to test, maintain, and extend.
Governance is equally important. A governed pipeline can document where data came from, who can access it, which transformations were applied, and what happens when a record fails validation. Monitoring and audit logs help teams investigate issues, while version control makes it easier to review changes to business rules.
This structure supports collaboration between technical and operational teams. Engineers can maintain connections, while authorized users manage approved workflow settings and review results. By automating routine requests and creating repeatable processes, teams can focus less on administration and more on data-driven operations.
How Does a Data Pipeline Differ From ETL and ELT?
A data pipeline is the broader system that moves data from one place to another and prepares it for use. It can collect information from databases, APIs, files, and business applications, then validate records, apply rules, trigger workflows, and deliver results to a warehouse, database, or operational system.
ETL and ELT describe two specific ways a pipeline transforms data. ETL transforms information before loading it into the destination. ELT loads raw information first and transforms it afterward. A pipeline may also include streaming, replication, synchronization, scheduling, monitoring, and error handling.
The best approach depends on what your business needs from its data. A reporting warehouse may benefit from batch ETL or ELT, while an order management process may require real-time synchronization between applications. As IBM explains, every ETL pipeline is a data pipeline, but not every data pipeline is an ETL pipeline.
Understanding these differences helps you choose the right architecture instead of treating every data movement project the same way. It also makes it easier to decide whether you need an analytics pipeline, an operational workflow, database replication, or a combination of approaches.
Extract, transform, and load with ETL
ETL stands for extract, transform, and load. The pipeline first collects data from sources such as databases, APIs, files, or SaaS applications. It then cleans and reshapes the information before sending it to a warehouse, reporting database, or other destination.
For example, an ETL process might extract customer records from Salesforce, standardize phone numbers, remove duplicates, convert dates into a consistent format, and load the finished dataset into a data warehouse. The destination receives data that is ready for analysis or reporting.
ETL works well when information needs strict preparation before storage. It can enforce a defined schema, filter sensitive fields, and prevent invalid records from reaching downstream systems. However, complex transformations can increase processing time and make it harder to reuse the original data. RudderStack’s ETL explanation offers a helpful overview of this sequence.
Extract, load, and transform with ELT
ELT stands for extract, load, and transform. Instead of preparing data before storage, the pipeline extracts raw information and loads it into a data lake, warehouse, or other scalable platform. Transformations happen later, usually when analysts, reports, or applications need a specific view of the data.
This approach preserves the original records, which helps teams apply different business rules over time. For example, a company might load raw order data from Shopify and QuickBooks into a central warehouse, then create separate models for finance, inventory, and customer analysis.
ELT is often a good fit for cloud data platforms with substantial storage and processing capacity. It simplifies ingestion and supports multiple downstream uses, but raw data still requires careful management. Teams need clear access controls, naming conventions, documentation, and transformation logic. RudderStack’s ELT overview explains how this approach loads data before transforming it.
Use ETL and ELT as pipeline patterns
ETL and ELT are processing patterns, not alternatives to the broader concept of a data pipeline. They help teams decide when and where transformation should happen. The right choice depends on data volume, destination capabilities, compliance requirements, reporting needs, and how often the data changes.
Use ETL when the destination requires clean, structured data or when sensitive fields must be filtered before storage. Use ELT when the destination can handle large datasets and your team benefits from keeping an untouched source copy. Some organizations use both, applying ETL to operational integrations and ELT to analytics workloads.
A pipeline can also include several stages and patterns. It might extract data from Salesforce, transform account fields, load them into an operational database, and replicate selected updates to another application. DBSync’s Cloud Workflow helps connect business systems and apply rules as data moves between them.
Compare data pipelines with workflow orchestration
A data pipeline moves and processes data. Workflow orchestration manages the tasks around that pipeline. An orchestration tool determines what should run, in what order, under which conditions, and what should happen if a task fails.
For example, an orchestrator may start an extraction job at midnight, wait for it to finish, run a validation step, launch a transformation, and send an alert if record counts fall below an expected threshold. It can also manage dependencies, schedules, retries, timeouts, and task history. Apache Airflow and Prefect are common examples.
These functions may overlap in modern data platforms, but the distinction remains useful. A pipeline describes the data path and processing logic, while orchestration coordinates the work around it. For application-to-application workflows, DBSync Cloud Workflow combines data movement with scheduling, business rules, and automation.
Compare pipelines with replication and synchronization
A traditional data pipeline often prepares information for a destination such as a warehouse or reporting system. Replication focuses on creating or maintaining a copy of data in another database or application. Synchronization goes further by keeping two or more systems aligned, sometimes in both directions.
For example, a one-way pipeline might send completed Salesforce opportunities to a warehouse each night. A replication process might copy database changes as they occur. A bidirectional synchronization workflow could keep customer and order information aligned between Salesforce and QuickBooks, while handling updates from either system.
The distinction matters because synchronization requires field mapping, conflict handling, duplicate prevention, and decisions about which system controls each value. DBSync’s SaaS Replication connects business applications, while its CDC and Database Replication capabilities support change-based data movement.
Choose ETL, ELT, streaming, or replication
Choose ETL when data must be cleaned, filtered, or structured before it reaches the destination. Choose ELT when you want to load raw data quickly and use the destination platform for transformation. Both patterns work well for analytics and reporting, particularly when data arrives in scheduled batches.
Choose streaming when applications need updates continuously as events occur, such as inventory changes, payment activity, or customer actions. Choose replication when the priority is maintaining a current copy of data in another database or system. Choose bidirectional synchronization when multiple applications need to exchange updates and remain aligned.
The practical decision comes down to latency, volume, data direction, system capabilities, and business risk. A nightly finance report may only need batch ETL, while order and inventory systems may require real-time replication. DBSync’s Replication Ops Platform supports these requirements through application workflows, database replication, and real-time data synchronization.
Which Data Pipeline Tools and Technologies Do You Need?
The right data pipeline stack depends on what your business needs to move, where the data must go, and how quickly it needs to arrive. A pipeline that connects Salesforce, QuickBooks, Shopify, and a reporting database will have different requirements from one that processes millions of events from connected devices.
Most dependable pipelines include several layers: connectors for ingestion, orchestration for workflow management, transformation tools for preparing records, storage for keeping data accessible, and monitoring for identifying problems. You may not need a separate tool for every layer. A unified platform can reduce the number of systems your team must configure, maintain, and troubleshoot.
Before choosing a technology, map each data source, destination, update frequency, transformation, and security requirement. This gives you a clearer view of the capabilities you need and helps prevent unnecessary tools from complicating your architecture.
Connect databases, APIs, SaaS platforms, and files
Your pipeline needs connectors that can access the systems your organization already uses. Common sources include SQL databases, REST APIs, SaaS applications, spreadsheets, CSV files, and event streams. Each source may have different authentication methods, field names, formats, and update patterns, so native connectors can save considerable development time.
For example, your sales team may manage customer records in Salesforce while finance uses QuickBooks. A connector can transfer relevant records between both systems without requiring employees to enter the same information twice. DBSync offers Salesforce integration and QuickBooks integration for connecting these business applications through configurable workflows.
When reviewing connectors, check support for incremental updates, custom fields, authentication, error handling, and the specific editions of each platform you use. Also confirm how often the connector can retrieve or send data. A tool that supports only scheduled exports may not meet a requirement for near-real-time synchronization.
Orchestrate and schedule workflows
Orchestration tools control how pipeline tasks run. They define task order, manage dependencies, schedule recurring jobs, and retry failed operations. A workflow might retrieve new orders, validate customer information, update an accounting system, and send a completion notification only after each earlier step succeeds.
Apache Airflow, Prefect, and cloud-native schedulers are common choices for complex engineering environments. They can coordinate tasks across multiple services, but they may require considerable configuration and technical maintenance. The right choice depends on your team’s skills, workflow volume, and need for custom code.
For business integrations, a visual workflow platform may be more practical than building every process from scratch. DBSync’s Cloud Workflow helps teams configure data movement and business logic across connected systems. Look for dependency management, scheduled and event-based triggers, retries, alerts, run history, and role-based permissions.
Stream data with messaging platforms
Streaming tools move records continuously as events occur instead of waiting for a scheduled batch. They suit use cases that require current information, such as payment events, inventory changes, website activity, and sensor readings. Messaging platforms can temporarily hold events and deliver them to one or more downstream services.
Apache Kafka, Amazon Kinesis, Google Cloud Pub/Sub, and Azure Event Hubs are widely used for event streaming. These technologies support high volumes, but they also introduce decisions about event ordering, delivery guarantees, retention, and duplicate messages. Your team should define how the system handles each issue before moving to production.
Streaming is not automatically the best choice. A finance report that refreshes once each night may work well with a batch process, while an inventory change that must appear in another application within seconds may require continuous processing. AWS explains data pipeline patterns for both batch and streaming use cases.
For database updates, change data capture identifies inserts, updates, and deletes as they happen. DBSync’s CDC and Database Replication capabilities help replicate changes without repeatedly copying entire databases.
Transform data with SQL and workflow tools
Raw data rarely arrives in a format that every destination can use. Transformation tools prepare records by cleaning values, standardizing formats, filtering unnecessary fields, combining sources, masking sensitive information, and adding useful context.
SQL works well when data already lives in relational databases or warehouses. Teams can use it to join tables, remove duplicates, calculate fields, and create destination-ready views. Workflow tools are more useful when transformations involve conditional rules, lookups, application logic, or actions across several systems.
For example, an order pipeline might convert currency values, standardize customer addresses, match products to internal IDs, and apply tax rules before sending the order to an ERP. IBM describes common data transformation tasks, including filtering, cleaning, merging, aggregating, and enriching data.
Choose transformation features that make business rules clear and maintainable. Reusable mappings, field formulas, validation rules, and test environments can help prevent a small change from causing problems across connected applications.
Store data in warehouses, lakes, and operational databases
A pipeline needs a destination suited to the way people and applications will use the data. Data warehouses support structured reporting and analytics. Data lakes store large volumes of raw or semi-structured information. Operational databases support application features and everyday business processes.
Some organizations use several destinations. Current customer and order data may be synchronized with an operational application, while historical records are loaded into a warehouse for reporting. A lakehouse can combine features of data lakes and warehouses for analytics and machine learning workloads.
Your storage choice should account for query patterns, retention requirements, access controls, data volume, and cost. It should also preserve enough context to show where records came from and when they were updated. IBM outlines common pipeline destinations, including databases, cloud warehouses, data lakes, and lakehouses.
When sending data to a business application, storage is not the only consideration. The destination may have API limits, required fields, validation rules, and record ownership settings. Build these requirements into the pipeline before it sends records.
Monitor logs, lineage, and data quality
A pipeline is not reliable simply because it runs without displaying an error. Monitoring should show whether data arrived on time, how many records were processed, which steps failed, and whether the output meets quality expectations.
Logs provide a record of pipeline activity, including request failures, rejected records, and transformation errors. Lineage shows where a field originated and how it changed before reaching its destination. Quality checks can identify missing values, duplicates, invalid formats, unexpected volume changes, and stale data.
Set alerts around the conditions that matter most to your business. A failed overnight accounting sync may need immediate attention, while a small number of rejected marketing records may follow a different response process. Dashboards should make it easy to inspect a failed run and identify affected records.
Monitoring data freshness, lineage, and quality helps teams catch issues before they affect reports or business operations. Choose tools that retain run history and let authorized users review errors without searching through separate systems.
Evaluate scalability, reliability, security, and cost
Before selecting a tool, assess how it will perform as your data volume, user count, and number of integrations grow. Review throughput limits, API quotas, concurrency options, storage requirements, and pricing based on records, tasks, compute time, or connections.
Reliability matters as much as speed. Look for retries, checkpoints, resumable jobs, failure notifications, and protection against duplicate processing. A dependable pipeline should continue operating when one component fails, or recover cleanly when service is restored. Validation checks at multiple stages help maintain data quality, as AWS recommends for resilient data pipelines.
Security requirements should cover encryption, credentials, access controls, audit logs, data retention, and compliance obligations. Also consider ongoing maintenance. A lower-cost tool may become expensive if your team must write custom connectors, maintain infrastructure, and investigate failures manually.
For organizations connecting many business systems, a complete platform can simplify this evaluation. DBSync’s Replication Ops Platform combines data movement and replication capabilities for teams that need governed, dependable flows across applications and databases.
How Do You Build a Reliable Data Pipeline?
A reliable data pipeline does more than move records from one system to another. It keeps information accurate, available, secure, and useful as your business grows. That means preparing for incomplete inputs, failed runs, changing schemas, rising data volumes, and the needs of the teams who rely on the data.
Start by defining what the pipeline needs to accomplish. Identify the source systems, destinations, required fields, acceptable latency, and business rules that shape each record. For example, a pipeline connecting Salesforce and QuickBooks may need to match customer IDs, standardize account names, and prevent duplicate invoices before sending data between platforms. DBSync supports these connected workflows through solutions such as Cloud Workflow, which helps teams coordinate data movement and business processes across applications.
Reliability also depends on visibility. Your team should be able to see whether a run succeeded, how many records it processed, which records failed, and when the destination was last updated. The AWS overview of data pipelines emphasizes quality checks, scalability, and dependable processing. Treat these capabilities as part of the pipeline itself, not as optional add-ons.
Resolve inconsistent formats, schemas, and APIs
Connected systems rarely represent information in exactly the same way. One application may store a phone number as plain text, while another expects a structured field. A CRM may use Company, while an accounting platform uses CustomerName. APIs may also differ in authentication methods, request formats, pagination rules, and rate limits.
Create a field map for every value that crosses systems. Define required fields, accepted formats, default values, and the action to take when data is empty or unsupported. Standardize dates, currencies, phone numbers, IDs, and status values before loading records into the destination. This approach helps maintain compatibility across diverse data sources, as NinjaCat explains in its overview of data pipelines.
Fix duplicates, missing records, and data quality issues
Poor-quality source data can spread quickly through connected systems. Duplicate contacts may create multiple customer accounts, missing product IDs can break order updates, and invalid values may cause a destination platform to reject an entire batch.
Build quality checks into each stage of the pipeline. Look for missing required fields, invalid values, duplicate records, unexpected formats, and relationships that do not match. Decide whether to reject, quarantine, or correct each issue. Keep rejected records in an error queue with enough context for someone to review and fix the source data. These checks reflect the practical recommendations in RudderStack’s data pipeline guide.
Validate, deduplicate, reconcile, and process data idempotently
Validation should happen before, during, and after processing. Before a load, confirm that records contain the fields and values the destination expects. During processing, check that transformations produce valid results. Afterward, compare source and destination counts, totals, or key fields to confirm that the transfer completed correctly.
Use dependable identifiers for deduplication whenever possible, rather than relying only on names or email addresses. Idempotent processing matters just as much. If a job runs twice, it should not create duplicate invoices, contacts, or orders. Stable keys, upserts, checkpoints, and reconciliation steps help ensure the same input produces the same final result. AWS recommends validation throughout a data pipeline to help maintain consistent data quality.
Recover from failed runs, partial loads, and errors
Failures are inevitable. An API may time out, a database connection may drop, or a destination platform may temporarily reject requests. A reliable pipeline handles these events without forcing your team to restart every step manually.
Use retries for temporary failures, with a delay between attempts and a limit on repeated requests. Checkpoint progress during large jobs so the pipeline can resume from the last successful step. For partial loads, record which items succeeded and which need another attempt. Send permanently failed records to a review queue, then alert the appropriate owner with a useful error message. RudderStack recommends retries, circuit breakers, fallback paths, and alerts to reduce manual intervention.
Manage schema drift and changing business rules
Source systems change over time. A platform may rename a field, add a status, change an API response, or retire an endpoint. Business rules change too. A sales team may introduce a new lead stage, while an accounting team may require a different tax treatment.
Monitor schemas and test changes before they reach production. Use versioned mappings so you can support old and new formats during a transition. Treat unexpected fields as signals to review, rather than silently discarding data. Keep transformations separate from connection logic where possible. This makes it easier to update a business rule without rebuilding the entire pipeline. RudderStack’s pipeline guidance also recommends detecting schema drift before it disrupts downstream processes.
Scale throughput, concurrency, latency, and resources
A pipeline that works for 10,000 records may struggle with 10 million. Plan for growth by measuring current data volume, processing time, API limits, and peak workloads. Set a freshness target, such as updating customer records within five minutes or completing a nightly financial load by a specific time.
Use controlled concurrency to process independent records in parallel while respecting rate limits and destination capacity. Separate workloads when possible, so a large historical backfill does not delay time-sensitive updates. Allocate resources based on actual usage, then review performance as volumes change. AWS identifies throughput, latency, and changing data volumes as important considerations for scalable pipeline design.
Optimize queries with parallel processing and partitioning
Database queries can become a major bottleneck when a pipeline repeatedly scans entire tables. Start with incremental extraction, using a reliable timestamp, sequence number, or change marker to retrieve only new and updated records.
Partition large datasets by date, customer range, region, or another useful key. Separate workers can then process smaller sections at the same time. Add indexes to columns used for filtering and joining, and select only the fields the destination requires. Test query plans before increasing concurrency, since parallel work can overwhelm the source database if it is not controlled. These techniques support higher throughput for large or rapidly growing data streams.
Secure data with governance, access controls, and encryption
Data pipelines often carry sensitive customer, financial, and operational information. Protect that data from the moment it leaves the source system until it reaches its destination. Use encryption in transit and at rest, and store credentials in a secrets manager rather than in scripts or configuration files.
Apply least-privilege access. Each connection should have only the permissions it needs, such as reading selected CRM fields or writing to a specific destination table. Keep an inventory of data sources, owners, retention rules, and permitted uses. Review access regularly, rotate credentials, and record important activity in audit logs. These practices align with RudderStack’s recommendations for access controls, encryption, and audits.
Monitor bottlenecks with logs, metrics, and alerts
Monitoring should answer three questions quickly: Is the pipeline running? Is it processing data correctly? Is the destination up to date? Track job status, duration, record counts, throughput, error rates, data freshness, and latency. Break these metrics down by source, destination, workflow, and processing stage to locate bottlenecks.
Logs should include run IDs, timestamps, record identifiers, action types, and error details, while avoiding unnecessary exposure of sensitive values. Set alerts for failed jobs, unusual volume changes, stale data, rising latency, and repeated API errors. A dashboard can show overall health, but alerts should reach the person responsible for fixing the issue. RudderStack identifies job duration, data volume, freshness, and latency as useful monitoring metrics.
Manage changes with version control, rollbacks, and runbooks
Treat pipeline code, SQL queries, field mappings, and configuration as managed assets. Store them in version control, review changes before deployment, and label releases clearly. This gives your team a record of what changed and makes it possible to restore a previous working version.
Test transformations with representative data before releasing them. Use separate development, staging, and production environments when practical. Create rollback procedures for failed deployments, and document how to pause a workflow, replay a failed batch, restore a connection, or handle a schema change. Runbooks should include owners, escalation contacts, common error messages, and recovery steps. Keeping these details current reduces dependence on one person and helps your team respond consistently when a pipeline needs attention.
How Can DBSync Support Data Pipeline Integration?
A data pipeline connects sources, processes, and destinations so information moves through your business without repeated manual work. That might mean sending customer details from Salesforce to an accounting system, syncing inventory between Shopify and Microsoft D365, or copying database changes into a reporting environment. Along the way, the pipeline can clean, standardize, validate, and enrich data before delivering it where teams need it.
DBSync supports these use cases through a combination of replication, workflow automation, application connectors, and change data capture. The Replication Ops Platform helps manage recurring data movement, while Cloud Workflow supports process-based automation. SaaS Replication connects business applications, and CDC and Database Replication helps transfer database changes with minimal delay.
Manage data movement with the Replication Ops Platform
The Replication Ops Platform helps teams manage recurring data movement across databases, applications, and other systems. You can define replication jobs, configure source and destination connections, and establish rules for how records move between environments.
This reduces reliance on spreadsheets, manual exports, and one-off scripts. It also gives your team a consistent way to manage data pipelines as requirements change. For example, you might create repeatable processes for reporting, operational databases, backups, or application integration. Centralized management can make it easier to review pipeline activity, identify issues, and maintain reliable data flows across connected systems. Explore the Replication Ops Platform to see how it can support managed data movement.
Orchestrate workflows with Cloud Workflow
Not every pipeline simply copies records from one system to another. Many require a sequence of actions, such as retrieving an order, checking customer information, applying business rules, updating an accounting record, and notifying another application.
DBSync Cloud Workflow helps coordinate these processes. Teams can build workflows that connect data sources, transform information, and trigger actions based on defined conditions. This can reduce manual handoffs and make repeatable processes easier to manage. Cloud Workflow can support scheduled jobs, event-based actions, and multi-step processes that coordinate several business systems. It is especially useful when a data transfer needs decisions or follow-up actions before it reaches its destination.
Connect business applications with SaaS Replication
SaaS applications often contain valuable operational data, but that information can become difficult to use when each platform operates separately. Sales activity may sit in a CRM, invoices in an accounting platform, and customer orders in an ecommerce system.
DBSync SaaS Replication helps connect these applications and replicate data between them. This gives teams a practical way to share records without relying on repeated downloads, uploads, or manual re-entry. You can make application data available for reporting, customer service, finance, and operations while keeping information more consistent across the tools your teams already use. The result is a more connected data environment, with integration rules that support your business processes.
Stream updates with CDC and Database Replication
When teams need current information, copying an entire database on a fixed schedule may not be the best approach. Change data capture, or CDC, identifies inserts, updates, and deletions as they occur, then sends those changes to another system.
DBSync’s CDC and Database Replication capabilities support pipelines that respond to database changes instead of waiting for a full batch process. This can help with operational reporting, data consolidation, application synchronization, and near-real-time analytics. By transferring relevant changes rather than repeatedly copying every record, CDC can reduce unnecessary processing and shorten the time between an update and its availability elsewhere. Teams can apply this approach when data freshness matters and source systems continue to change throughout the day.
Connect Salesforce and QuickBooks
Salesforce and QuickBooks often contain complementary information. Salesforce may hold leads, accounts, opportunities, and customer activity, while QuickBooks stores invoices, payments, products, and financial records. When these systems are disconnected, employees may spend time re-entering information or checking which platform contains the latest details.
DBSync can support a Salesforce integration alongside QuickBooks workflows. For example, a won opportunity could start a customer or invoicing process in QuickBooks, while payment information could become available to sales and service teams. The right setup depends on your data model, permissions, and business rules. Define which system owns each record, then configure the pipeline to move only the fields and events that other teams need.
Connect Microsoft D365 and Shopify
Microsoft D365 and Shopify support different parts of a commerce operation. Shopify manages storefront activity, orders, customers, and product interactions, while Microsoft D365 can support enterprise resource planning, inventory, finance, and fulfillment processes.
A DBSync integration solution can connect these customer-facing and back-office systems so information moves between them more consistently. Order data can flow into the appropriate operational process, while product, inventory, or fulfillment updates can return to the storefront. This reduces manual reconciliation and gives teams a clearer view of orders and inventory across platforms. Before setting up the connection, document how product identifiers, stock levels, order statuses, and customer records correspond in each system.
Synchronize systems in real time, in both directions
Some integrations need more than a one-way export. If users update records in multiple systems, changes must travel in both directions without creating duplicates, conflicting updates, or accidental overwrites.
DBSync supports real-time bidirectional synchronization across connected systems. A change in one application can trigger an update in another, based on the rules you define. This can help sales, finance, support, and operations teams work with shared information without forcing every team into the same application. Before implementing bidirectional sync, identify the system of record for each field, establish conflict rules, and decide which updates should move immediately. Clear ownership rules are essential for keeping synchronized data trustworthy.
Match DBSync capabilities to pipeline, replication, and workflow needs
The right DBSync configuration depends on what your pipeline needs to accomplish:
- Use the Replication Ops Platform to manage recurring data movement and replication jobs across systems.
- Use Cloud Workflow when data must pass through conditions, transformations, schedules, or multi-step business processes.
- Use SaaS Replication to connect CRM, accounting, ERP, ecommerce, and other business applications.
- Use CDC and Database Replication when database changes need to move continuously or with minimal delay.
- Use bidirectional synchronization when teams update connected systems and need those changes to remain aligned.
Start by listing your data sources, destinations, required latency, direction of movement, transformation rules, and error-handling needs. Then map each requirement to the DBSync capability that fits it. This approach helps your team build a more deliberate integration plan instead of creating a separate custom process for every data flow.
Frequently Asked Questions
What is the main purpose of a data pipeline?
A data pipeline automates the movement of information between systems and prepares it for use. It can help teams keep CRM, accounting, ERP, ecommerce, databases, and reporting tools aligned while reducing manual entry and improving data accuracy.
What is the difference between a data pipeline and data integration?
Data integration is the broader practice of connecting systems and combining information. A data pipeline is the automated path that collects, processes, validates, and delivers that information. Integration may use one or more pipelines to support a specific business process.
Should I use batch processing, real-time processing, or CDC?
Use batch processing when updates can happen on a schedule, such as nightly reporting or periodic imports. Real-time processing is better when teams or applications need updates shortly after an event. Change data capture, or CDC, is useful when you need to transfer database inserts, updates, and deletions without repeatedly copying entire tables.
How can I make a data pipeline reliable?
Define clear field mappings, validate records, prevent duplicates, and establish ownership for important data. Your pipeline should also include retries, checkpoints, error queues, monitoring, alerts, and recovery procedures. Regular reconciliation helps confirm that source and destination records remain consistent.
How can DBSync help with data pipeline integration?
DBSync provides tools for application workflows, SaaS replication, database replication, and real-time bidirectional synchronization. Businesses can use it to connect platforms such as Salesforce, QuickBooks, Microsoft D365, Shopify, and databases, while applying transformation rules and managing recurring data flows through a centralized platform.