Your nightly SQL Server extract takes eleven minutes and moves 40,000 rows. Maybe 200 of them actually changed. The other 39,800 get re-read, re-transformed, and re-loaded because nothing told your pipeline which rows were new. That’s the problem Change Data Capture (CDC) solves in SQL Server: instead of re-scanning a table to find what’s different, […]
Best Salesforce Replication Tool in 2026
An honest, feature-first comparison for teams that need Salesforce data living in their own database or warehouse. TL;DRThe best Salesforce replication tool depends on your goal. DBSync Cloud Replication leads for teams that need a queryable, bidirectional copy of Salesforce inside their own database for reporting, backup, and disaster recovery. Fivetran and Skyvia suit warehouse-only […]
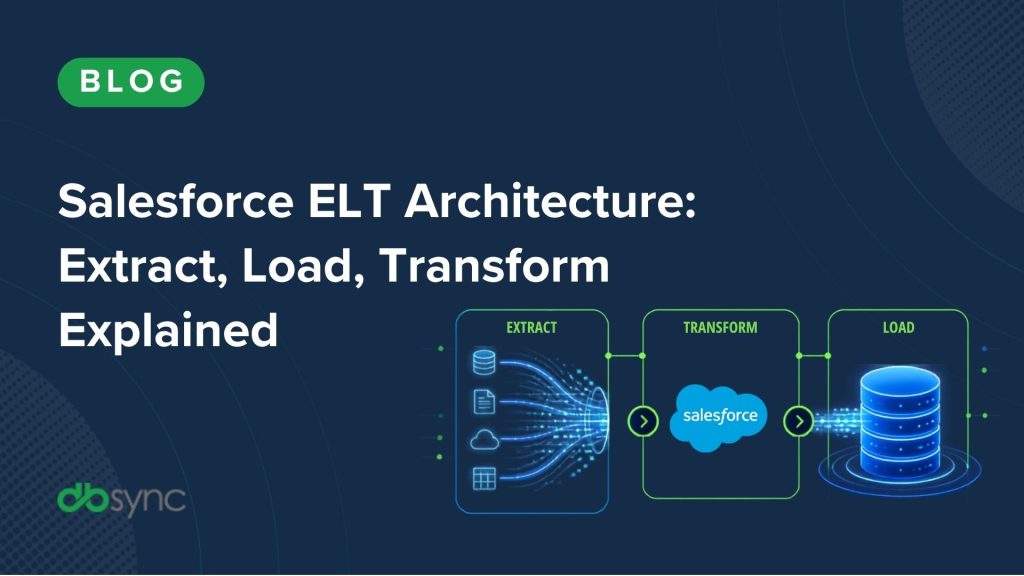
Salesforce ELT: Extract, Load & Transform Salesforce Data
What is Salesforce ELT? Salesforce ELT is the process of pulling data out of Salesforce (Extract), writing it into a destination in something close to its raw form (Load), and only then reshaping it into its final structure (Transform) using the compute power of the destination system itself, rather than a separate transformation engine sitting […]
Salesforce Data Pipeline: How to Build a Scalable Data Integration Pipeline
What is a Salesforce data pipeline ? A Salesforce data pipeline is the set of processes that move records into, out of, and between Salesforce and the other systems your business runs on ERPs, data warehouses, marketing platforms, support desks. At small volumes, people handle this with reports and manual exports. Once you’re pushing tens […]
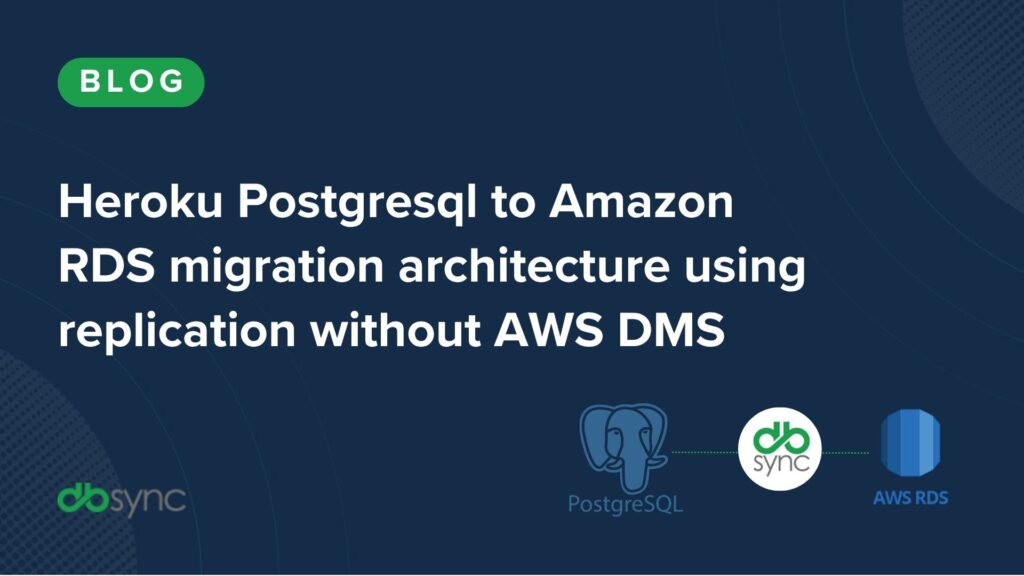
Moving Heroku Postgres to Amazon RDS: What Actually Works When You Don’t Have Superuser
You’ve decided to move. You open the AWS Database Migration Service documentation, follow it carefully, and about twenty minutes in, you hit a wall: DMS wants a user with the REPLICATION role, and Heroku won’t give you one. That’s not a configuration mistake. Heroku Postgres doesn’t grant customers the superuser role, and it doesn’t let […]
Data Integrity 101: Types, Threats, and Best Practices
Get clear answers on data integrity, including types, common threats, and best practices to keep your business data accurate, consistent, and reliable.
SQL Server to Databricks Replication
A step-by-step setup guide: connect SQL Server, configure Databricks, run the sync, and automate it. Companion to the webinar recording: This guide is the written companion to the SQL Server-to-Databricks replication webinar. It stands on its own: use it to set up and run the sync end to end, whether or not you watched the […]
Data Pipeline 101: How It Works and Why It Matters
A data pipeline automates how information moves between systems. Learn how data pipelines work, key benefits, and tips for building reliable workflows.
What Is Data Profiling? Techniques, Metrics & Why It’s the First Step in Data Quality
The migration was scheduled for Saturday night. Nobody profiled the data first. By Monday: 4,000 duplicate accounts, three date formats fighting over one field, and a free-text “Notes” column that turned out to contain credit card numbers. All of it was findable in advance. In about an hour. That hour is called data profiling. In […]
HubSpot CRM Replication: What It Is, How It Works, and Why Your Data Team Needs It
HubSpot CRM replication is the process of copying HubSpot CRM data into another database, data warehouse, or analytics platform while preserving original records. It gives data teams access to CRM data for analytics, reporting, and business intelligence without relying on HubSpot as the primary source for every query. This guide will walk through what HubSpot […]