Salesforce Data Pipeline: How to Build a Scalable Data Integration Pipeline
What is a Salesforce data pipeline ?
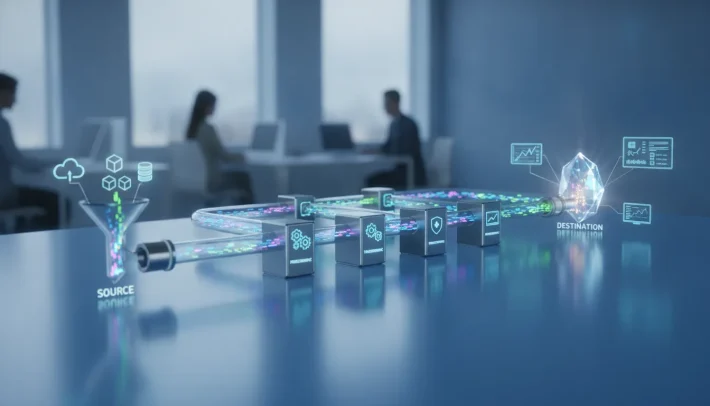
A Salesforce data pipeline is the set of processes that move records into, out of, and between Salesforce and the other systems your business runs on ERPs, data warehouses, marketing platforms, support desks. At small volumes, people handle this with reports and manual exports. Once you’re pushing tens of thousands of records a day, or feeding a BI warehouse that finance actually depends on, you need something that runs on a schedule, recovers from failures on its own, and doesn’t fall over the moment Salesforce changes a field type.
That’s the difference between “we move data out of Salesforce sometimes” and an actual pipeline: repeatability, monitoring, and a plan for what happens when something breaks at 2 a.m.
Why replication is the backbone of a scalable pipeline
Most of the pain in Salesforce integrations doesn’t come from the first sync it comes from the tenth, the hundredth, the one that runs after someone renamed a custom field. Replication is what keeps a downstream system (a warehouse, a reporting database, another SaaS app) in sync with Salesforce without you re-pulling the entire org every time.
A well-built replication layer gives you three things a one-off export never will:
- Incremental updates: only the records that changed since the last run get pulled, not the whole object
- Schema resilience: new fields or objects don’t silently break downstream reports
- Auditability: you can point to exactly when a record synced and what changed
Without this, teams end up with nightly full-table dumps that get slower every quarter, or brittle scripts that need a developer every time Salesforce ships a release.
Batch replication vs. CDC and where Salesforce fits
This is the part most vendor pages gloss over, so it’s worth being direct about it.
Change Data Capture (CDC) is a technique where a system reads database transaction logs directly and streams every insert, update, and delete the instant it happens. It’s the gold standard for database-to-database replication Postgres to Postgres, SQL Server to a warehouse, and so on because the source database exposes those logs natively.
Salesforce isn’t a raw database you can tap a transaction log on. It’s a multi-tenant SaaS platform that exposes data through APIs REST, Bulk API 2.0, SOQL queries with governor limits on how much you can pull and how often. Salesforce does offer its own event-based Change Data Capture product for near-real-time notifications, but that’s a Salesforce platform feature with its own licensing and setup, separate from what most third-party replication tools do.
Where DBSync stands on this: DBSync Cloud Replication does not perform CDC for Salesforce replication. What it does instead is scheduled, incremental replication polling Salesforce via SOQL on a configurable interval (as frequently as every few minutes, depending on your plan and API limits) and pulling only records where LastModifiedDate (or an equivalent tracking field) has changed since the last successful run. CDC-style log-based replication is something DBSync applies to database-to-database syncs, where the source system actually exposes transaction logs to read from.
The practical difference: instead of “instant” push notifications on every field change, you get near-real-time, interval-based syncs that are predictable, don’t hammer your API limits, and are easy to monitor. For the vast majority of reporting, warehousing, and cross-system sync use cases, that trade-off is invisible a five-minute polling interval feels real-time to anyone looking at a dashboard.
If your use case genuinely requires sub-second event propagation (triggering an external system the instant a Salesforce record changes), that’s a job for Salesforce’s own Platform Events or CDC feature, not a third-party replication layer and it’s worth saying that plainly rather than overselling what any replication tool can do.
Common bottlenecks in Salesforce data pipelines
A handful of problems show up in almost every Salesforce pipeline that outgrows its original design:
API limits. Salesforce enforces daily API call caps based on your edition and license count. Pipelines that re-query full objects instead of filtering by last-modified timestamps burn through this budget fast, especially on high-volume objects like Opportunity or Case.
Governor limits on bulk jobs. Bulk API jobs have their own batching rules too many small batches and you’re paying overhead on every call; too few large batches and a single failure invalidates a huge chunk of work.
Schema drift. Admins add custom fields, rename picklist values, or delete objects without warning a pipeline exists downstream. If your integration hardcodes field mappings, this breaks silently.
Relationship complexity. Salesforce’s object model is deeply relational Accounts, Contacts, Opportunities, custom objects with lookups running in every direction. A pipeline that syncs objects independently, without respecting parent-child order, ends up with orphaned records downstream.
Retry and failure handling. Networks drop, tokens expire, Salesforce has maintenance windows. A pipeline without built-in retry logic and dead-letter handling for failed records turns a five-minute outage into a data integrity project.
Building the pipeline: a practical structure
Here’s the shape a scalable Salesforce data pipeline usually takes, regardless of which tool sits underneath it:
- Define the object scope. Start with the objects that actually feed a business decision Accounts, Opportunities, Cases rather than replicating the entire org on day one.
- Set your sync cadence per object. High-change objects (Opportunity, Case) might run every 5–15 minutes; slower-moving reference data (Product, Price Book) can run hourly or daily.
- Map fields explicitly, including custom ones. Don’t rely on auto-mapping alone for anything a report depends on verify picklist and custom field mappings by hand at least once.
- Handle relationships in dependency order. Sync parent objects before children so foreign keys resolve on the first pass instead of generating orphan rows you have to reconcile later.
- Build in incremental filters. Use LastModifiedDate (or a custom tracking field) so every run only touches changed records, not the whole table.
- Add monitoring and alerting. You want to know a sync failed within minutes, not when someone notices the dashboard is stale three days later.
- Test schema-change resilience. Add a field in a sandbox, rerun the pipeline, and confirm it degrades gracefully instead of failing the whole job.
This is essentially the configuration model behind DBSync Cloud Replication: object-level scheduling, incremental SOQL-based polling, and dependency-aware sync order, without requiring custom code for the plumbing.
Best practices for keeping it scalable as volume grows
- Right-size your batch windows. Smaller, more frequent batches recover faster from failure than one giant nightly job.
- Separate reporting replicas from operational syncs. A warehouse feeding BI dashboards has different freshness requirements than a system that triggers downstream workflows.
- Version your field mappings. Treat mapping configuration like code track changes, so a bad mapping update is easy to roll back.
- Watch your API consumption trend, not just today’s usage. A pipeline that’s fine at 60% of your daily API limit today will fail quietly once your org grows.
- Plan for Salesforce release windows. Salesforce ships three major releases a year; test your pipeline against sandbox previews before each one goes live in production.
Frequently asked questions
Does DBSync support CDC for Salesforce replication? No. DBSync Cloud Replication uses scheduled, incremental polling via SOQL for Salesforce not log-based Change Data Capture. CDC is available for database-to-database replication scenarios, where the source system exposes transaction logs directly.
How often can Salesforce data be replicated without hitting API limits? It depends on your Salesforce edition’s daily API allocation and how many objects you’re syncing, but most orgs can run incremental, filtered syncs every 5–15 minutes comfortably. Full-object re-pulls should run far less often, if at all.
What’s the difference between batch replication and real-time sync? Batch (or incremental polling) replication checks for changes on a schedule every few minutes, hourly, or daily. Real-time sync, by contrast, pushes changes the instant they happen, typically through event streams or CDC. For Salesforce specifically, true real-time push requires Salesforce’s own Platform Events or CDC feature rather than a third-party polling tool.
Do I need custom code to build a Salesforce data pipeline? Not necessarily. Tools built specifically for Salesforce integration, including DBSync Cloud Replication, handle SOQL querying, field mapping, and scheduling through configuration rather than custom scripts. Code is usually only needed for unusual transformation logic.
What happens to a pipeline when Salesforce changes a field or object? A well-built pipeline should flag the mismatch and pause or alert rather than fail silently. This is why explicit field mapping and monitoring matter more than any single sync mechanism. Schema drift is inevitable at scale, and the pipeline’s job is to surface it quickly rather than avoid it entirely.
The bottom line
A scalable Salesforce data pipeline isn’t about picking the flashiest sync mechanism it’s about incremental updates that respect API limits, field mappings that survive schema drift, and monitoring that catches failures before they become a data integrity problem. CDC has its place for database-to-database replication, but for Salesforce, dependable scheduled polling done well is what actually holds up at scale.